A project can look finished on paper and still be unready for real life.
Testing is complete, the launch date is booked and communications are drafted. Then someone asks: Who handles the first support request on Monday morning?
The room goes quiet.
That question exposes the gap between delivery readiness and operational readiness. Delivery readiness asks, “Did we build what we agreed?” Operational readiness asks, “Can people run, support and improve this service once the project team steps back?”
Both matter. A successful go-live needs more than a completed deliverable.
Why operational readiness matters
Projects are temporary, but services continue. Without clear ownership, training, support, contingencies and measures, the project team becomes the unofficial support team and operational knowledge stays in people’s heads.
PMI’s guidance on project closing warns about this exact handover gap. The people who will operate and maintain a deliverable need appropriate training, awareness, tools and a clear commitment to their new responsibilities.
Public digital-service guidance makes the same point: live services need monitoring, availability, security, quality assurance and improvement. Microsoft also treats training, support transition, monitoring and hypercare as readiness work.
Operational readiness is therefore not another document to produce. It is evidence that the receiving team can operate the new service under normal conditions and respond when conditions are not normal.
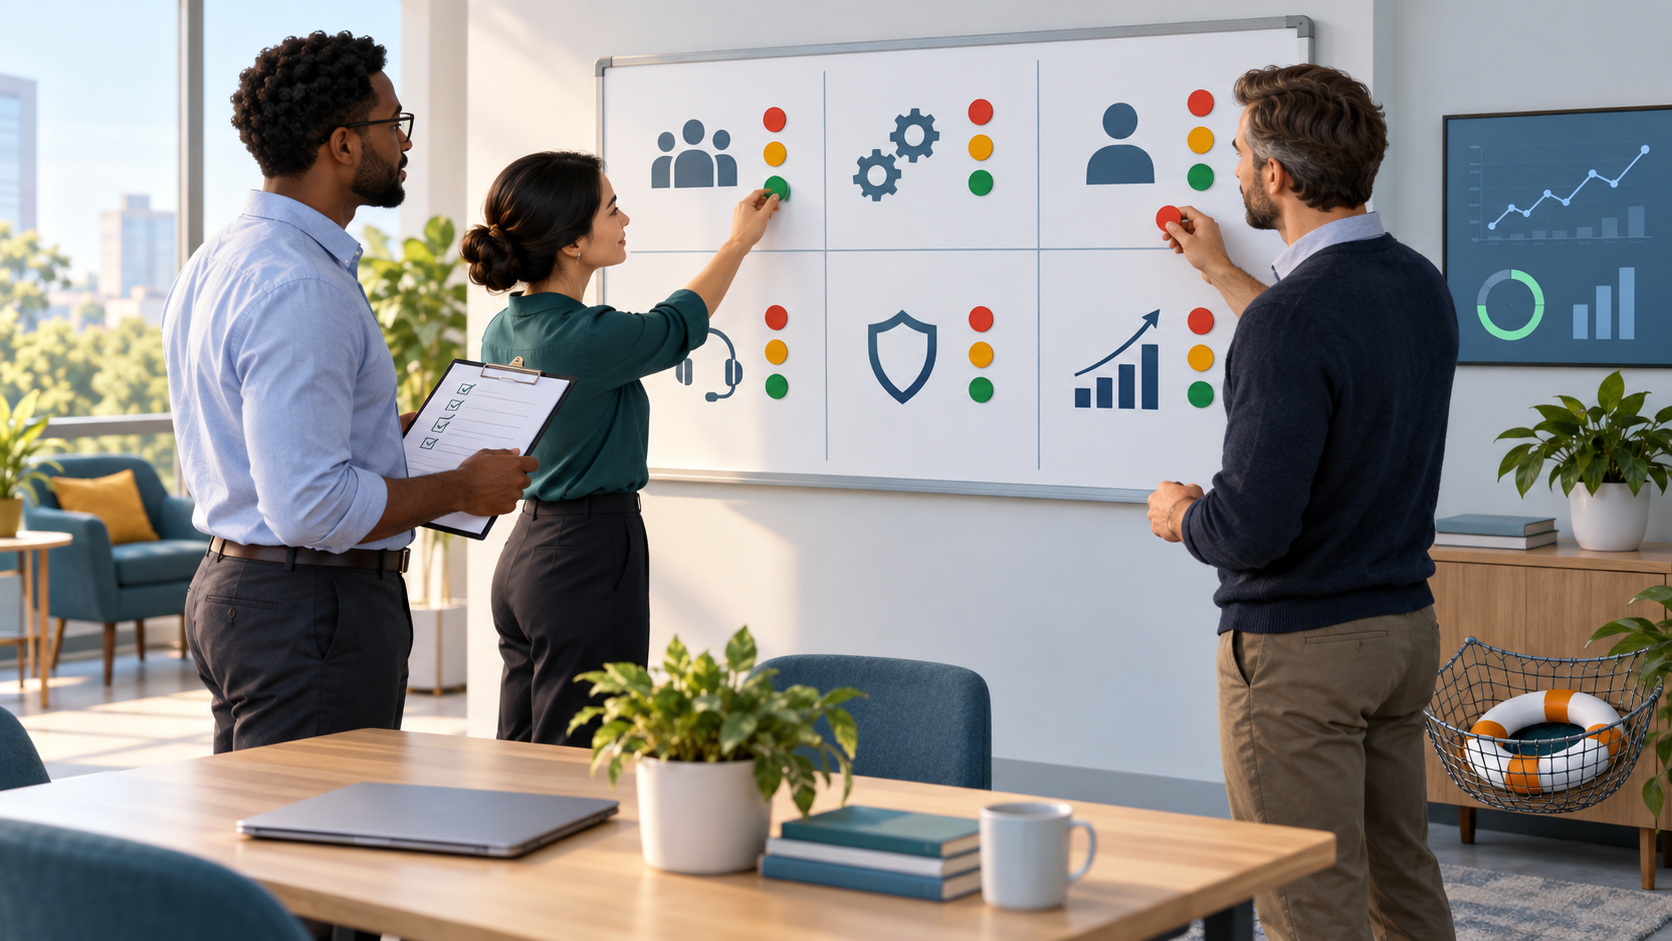
A simple six-part readiness check
Use the following six areas as a practical conversation. They apply to technology releases, new reporting processes, service redesigns, policy changes, workflow changes and other project outputs that move into business as usual.
For each area, record an owner, the evidence available and a red–amber–green rating.
- Green: ready, with evidence.
- Amber: workable gap with an owner and agreed completion date.
- Red: material risk to safe or reliable operation; resolve or formally accept before go-live.
A rating is not useful without evidence. “Training is on track” is an opinion. “Thirty-two of 35 users completed training, three sessions are booked, and the team leader has accepted the residual plan” is evidence.
1. Ownership and decision rights
Name the person accountable for the live service or process. Then identify who makes operational decisions, who approves urgent changes and who accepts unresolved risks.
Name a real role with authority, time and access—not a committee. Confirm that the owner understands and accepts the responsibility.
Ask:
- Who owns performance after go-live?
- Who can make a decision during an incident?
- Which unresolved risks has the operational owner accepted?
- When does project accountability formally transfer?
2. People and capability
Confirm that the people doing the work have practised it, not merely received information about it. Training attendance is useful, but capability is better demonstrated through a realistic task, scenario or supervised run.
Include frontline, supervisory, support and relief roles. Check changed workloads and early-life capacity.
Ask:
- Can each role complete its critical tasks?
- Have support staff practised common and difficult scenarios?
- Are job aids easy to find at the point of need?
- Is extra capacity available during the early support period?
3. Process, documentation and access
Walk through the end-to-end process as it will actually operate. Check hand-offs, approvals, data inputs, access permissions, records, templates and dependencies.
A project folder is not an operating guide. Keep essential instructions short, current and owned. Test links and permissions using a real user’s access.
Ask:
- Is there one current operating procedure or runbook?
- Do users and support staff have the right access?
- Are hand-offs and escalation points clear?
- Who updates the documentation when the process changes?
4. Support and incident response
Define how people ask for help and how the team responds. Publish one support route where possible. Clarify hours, priority definitions, response expectations, escalation contacts and the information users should provide.
Simulate a high-impact problem while the usual expert is unavailable. Can the team identify the owner, assess impact, communicate and coordinate a response?
Atlassian highlights visible ownership and mapped dependencies during incidents. Responders need to know what is affected, who owns it and what depends on it.
5. Contingency and recovery
Assume something important will not work as expected. Decide in advance what would trigger a pause, rollback, workaround or escalation.
A contingency is more than “contact the project team”. It should state the trigger, decision-maker, steps, communication route and safe operating position. Test the highest-risk recovery step before go-live where practical.
Microsoft recommends failure-mitigation options such as rollback or feature disablement. For a process change, the equivalent might be a manual queue, temporary approval path or phased release.
Ask:
- What conditions would make us stop or reverse the change?
- Who can authorise that decision?
- Has the fallback been tested?
- How will affected teams know which process to follow?
6. Measures and early review
Choose a small set of measures that will show whether the service is operating as intended. Include both outcomes and early warning signs.
Measures might cover demand, completion time, backlog, errors, support requests or adoption. Establish a baseline and thresholds that trigger action.
The Australian Government Digital Service Standard calls for a baseline, meaningful indicators, reporting and improvement. The aim is to notice quickly when reality differs from the plan.
Schedule the first review before go-live. Agree who will examine the evidence, how often the team will meet during the early period, and when the service can leave hypercare.
Run the readiness review in 45 minutes
Invite the operational owner, project lead, frontline and support representatives, and critical dependency owners.
Step 1: Set the test — 5 minutes
State the change, planned go-live and what “ready” means. Use one sentence: “The receiving team can operate, support and monitor the service without relying on informal project-team knowledge.”
Step 2: Review the six areas — 24 minutes
Spend four minutes per area. Record evidence, rating, gap, owner and due date. Use the lower rating until evidence resolves disagreement.
Step 3: Test one failure scenario — 8 minutes
Choose the most credible disruption. Walk through detection, decision-making, communication, workaround and recovery. Note missing contacts, access or instructions.
Step 4: Make the decision — 5 minutes
Choose one outcome: go, go with agreed conditions, or not yet. Do not hide a red item inside a long action list. If leaders accept a red risk, record who accepted it and why.
Step 5: Book the first review — 3 minutes
Set the early-life review date, measures and attendees. Confirm the route for reporting problems from day one.
A realistic workplace example
A health-service operations team is introducing an administrative referral-status dashboard. Data flows correctly and users can open it. Technically, the project is ready.
During the operational readiness review, the team finds three gaps. Weekend supervisors do not have access. The service desk has no support article. Nobody has agreed what happens if the dashboard data is delayed.
The team rates access amber, support red and contingency red. It assigns owners, tests a manual fallback, gives the service desk a diagnostic guide and fixes weekend access.
The launch proceeds two days later. The difference is not more testing of the dashboard itself. It is proof that the surrounding service can cope when help is needed or information is late.
Common mistakes to avoid
Treating the checklist as a box-ticking exercise
A completed field is not evidence. Ask someone from the receiving team to demonstrate the process or explain what they would do.
Running the review too late
Do not wait until the day before launch. Hold an initial review early enough to fix gaps, then repeat it close to go-live.
Focusing only on technology
A system can work while the service fails because people, workload, communications, policy, access or support arrangements are not ready.
Leaving ownership with the project manager
The project manager can coordinate the transition, but the operational owner must accept the service, residual risks and ongoing decisions.
Using AI as the approver
AI can organise questions, summarise a workshop or challenge missing scenarios. It must not approve go-live. Use only approved tools and keep sensitive information, judgement and risk acceptance with authorised people.
Try This This Week
Pick one project or change approaching launch. Create a one-page table with these columns:
- Readiness area
- Evidence
- Rating
- Gap or decision
- Owner
- Due date
Run a 45-minute review using the six areas. Finish with a clear go, go with conditions, or not-yet decision. Then book the first operational review before everyone leaves the room.
If the launch is still weeks away, that is even better. Readiness work is most useful when there is time to act on what you find.
Key takeaway
Go-live is not the moment a project proves it has finished. It is the moment the organisation proves it can operate what the project delivered.
A practical operational readiness review connects the deliverable to real ownership, capable people, usable instructions, support, recovery and measurement. That is what turns a successful project output into a sustainable service.
Connect with Raf on LinkedIn for practical ideas on project delivery, responsible workplace AI and continuous improvement. Read the full article on rafsanga.com once published.
AI tools assisted with research and drafting. The final article was reviewed and approved by the author.
Sources and further reading
- Project Management Institute — Project closing: why transition to business as usual matters
- Australian Government Digital Service Standard — Criterion 9: Monitor your service
- UK Government Service Manual — How the live phase works
- Microsoft Learn — Use the go-live checklist to make sure your solution is ready
- Microsoft Learn — Operational Excellence recommendation checklist
- Atlassian Support — How services work with incidents
Comments
Post a Comment